
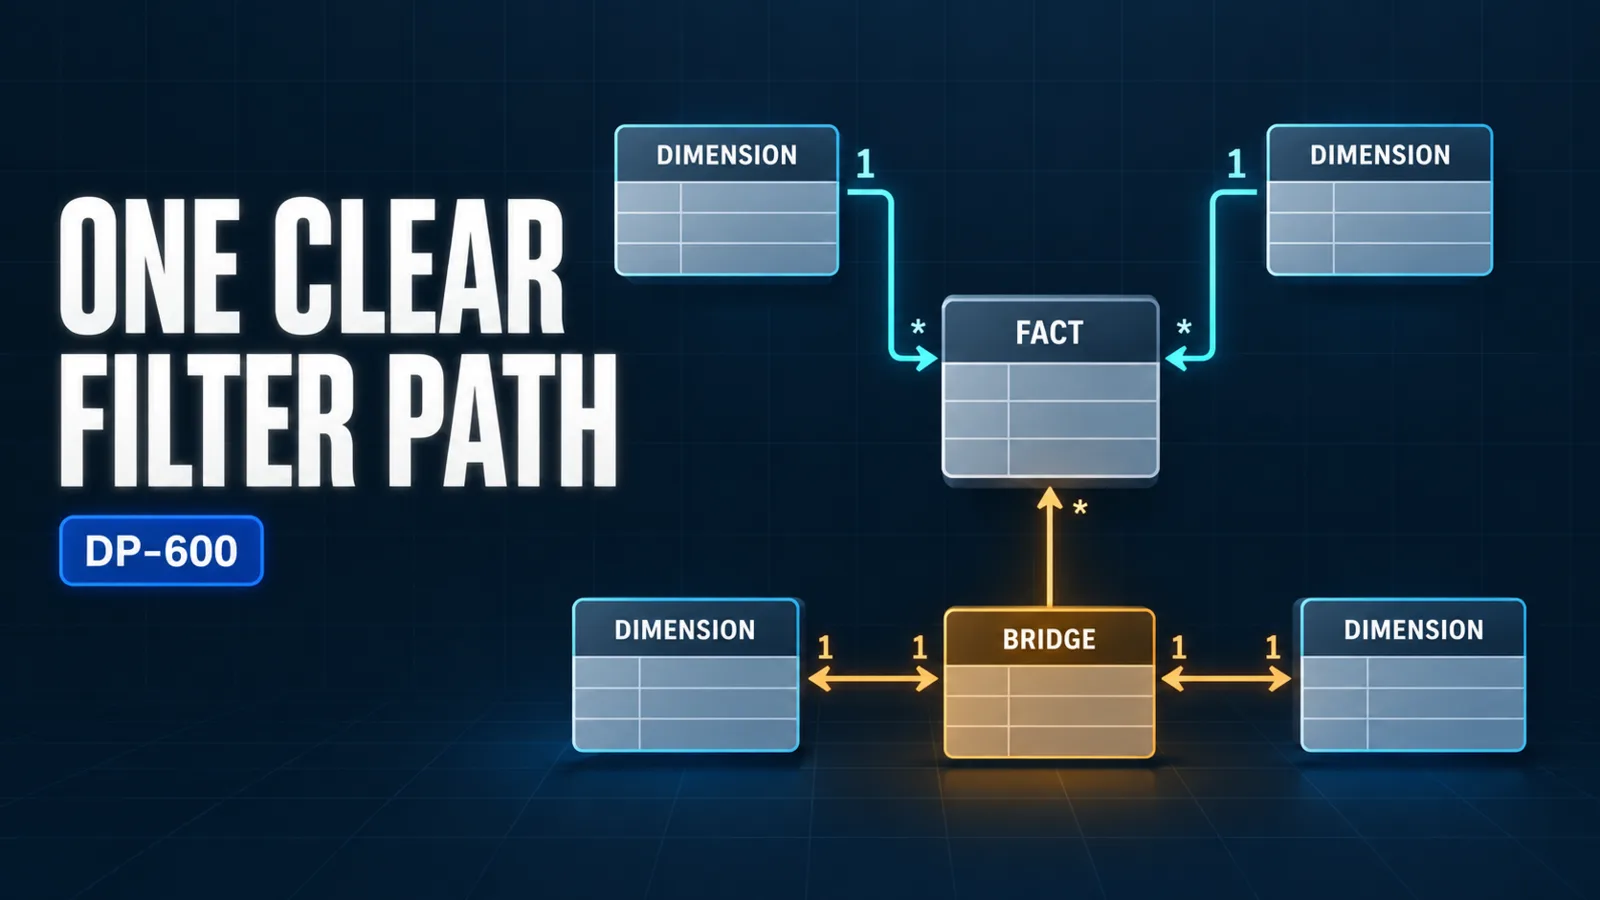
A reliable Power BI semantic model uses a star schema whose dimension tables have unique keys, whose fact tables retain a declared business grain, and whose relationships express intentional one-to-many filter paths. Filters should normally travel from dimensions to facts. When a business concept is genuinely many-to-many, an explicit bridge table should resolve the association and expose one understandable path through the model rather than relying on ambiguous direct relationships or broad bidirectional filtering.
That architecture turns physical analytical tables into trustworthy business semantics. The semantic layer gives report authors consistent entities, attributes, and paths for slicing facts, while measures consume those paths predictably. It does not replace the physical dimensional design of a lakehouse or Warehouse, define advanced Data Analysis Expressions (DAX), or choose a semantic-model storage mode; it governs how prepared tables behave as a reusable analytical model.
Semantic-Model Architecture Overview
Microsoft's star-schema guidance for Power BI separates tables by modeling role: dimension tables support filtering and grouping, while fact tables support summarization. A semantic model should preserve that separation even when its source is already a dimensional Fabric Warehouse or a curated lakehouse layer.
The core analytical path is:
- A user selects an attribute from a dimension, such as fiscal year, product category, or customer segment.
- A relationship propagates that filter from the dimension's unique key to matching foreign-key values on a fact table.
- The fact table is reduced to rows at its declared grain.
- A governed measure summarizes those rows and returns a business result.
Every relationship participates in this path. Cardinality declares which side is unique, cross-filter direction declares where filters may travel, and active status determines which path Power BI uses by default. Trustworthy analysis depends on those declarations matching the data rather than merely allowing the model to load.
Give Each Table One Clear Role
Dimension tables define business context
A dimension should represent a stable analytical subject such as Date, Product, Customer, Geography, or Account. Its key column on the one side of a relationship must contain one distinct value per member. Descriptive columns provide the names, categories, hierarchies, and sort attributes that users place on slicers and visual axes.
Good semantic design also makes the intended business vocabulary obvious. Hide technical keys that users should not aggregate, use unambiguous display names, apply consistent formats, and organize related fields so that two report authors interpret the same entity in the same way. If a dimension key is not unique, correct the source or introduce an appropriate semantic structure; changing the declared cardinality to suppress an error changes the meaning of the model.
Fact tables preserve an analytical grain
A fact table records events, snapshots, or other measurable observations. Its foreign keys connect each fact row to dimensions, and its numeric columns or measures support aggregation. The semantic model must not imply a finer or coarser grain than the prepared table actually contains.
For example, a sales fact at order-line grain can be filtered by Product, Customer, and Date dimensions. A monthly inventory snapshot has a different grain and should remain a separate fact table even if it shares those dimensions. Joining two facts directly because they share a business label commonly duplicates rows or creates an unclear filter path; shared conformed dimensions provide the safer analytical coordination point.
Physical choices such as surrogate-key generation, slowly changing dimension processing, denormalization, and gold-layer construction belong upstream. DP-600: Dimensional Modeling for Fabric Lakehouses and Warehouses covers that physical analytical-store boundary. The semantic model should validate and expose the resulting roles rather than conceal unresolved grain or key problems.
Set Cardinality from Verified Key Behavior
Cardinality is a data contract, not a convenience setting. Use the relationship shape that the key behavior proves:
| Relationship shape | Appropriate condition | Main design concern |
|---|---|---|
| One-to-many | The dimension-side key is unique and the fact-side key can repeat | Preferred star-schema path from a dimension to a fact |
| One-to-one | Both related columns are unique | Confirm that splitting the entity across tables provides real value |
| Many-to-many | Neither related column is unique, or the business association itself has multiple members on both sides | Make the association and filter semantics explicit, usually with a bridge |
Before creating a relationship, profile the keys for uniqueness, blanks, unmatched values, and accidental type differences. A declared one-to-many relationship cannot compensate for duplicates on the one side. Unmatched fact keys also need a documented business treatment because they can make totals appear while the corresponding dimension member is absent from grouped results.
Use one-to-one relationships sparingly. If two tables describe the same entity at the same grain, combining them upstream can produce a simpler model. Keep them separate only when there is a deliberate semantic, ownership, or source constraint.
Control Filter Direction and Path Ambiguity
Single-direction filtering from a dimension to a fact is the clearest default. It matches the star-schema question—"which fact rows belong to the selected dimension members?"—and limits the number of paths a filter can follow.
Bidirectional cross-filtering can be appropriate when a verified business interaction requires filters to travel both ways, particularly in a carefully designed bridge pattern. It should be a local exception with a testable reason. Enabling it broadly can let one fact influence another through shared dimensions, create ambiguous paths, and make a visual's result depend on relationships that report authors cannot see.
For every proposed bidirectional relationship, ask:
- Which user selection must reach which target table?
- Is there already another active route between those tables?
- Could a fact table begin filtering a dimension and then another fact?
- Can the requirement be met with a clearer bridge or a calculation-specific technique instead?
- Do detail rows, subtotals, and grand totals remain correct under combined slicers?
Multiple possible routes between the same tables are a warning that the model needs an explicit path decision. Keep the normal business route active. Alternative valid routes, such as Order Date and Ship Date, should be named and handled deliberately rather than activated into ambiguity. The DAX implementation of an alternate-path calculation belongs in DP-600: Advanced DAX Patterns for Enterprise Semantic Models.
Resolve Many-to-Many Semantics with Bridge Tables
A bridge table represents a real association at a declared grain. Typical examples include customers associated with multiple accounts, employees assigned to multiple projects, or products carrying multiple classifications. The bridge contains one row per valid association, normally using the keys of the participating dimensions.
Consider customer analysis over account transactions:
- Customer has one row per customer.
- CustomerAccount has one row per valid customer-account association.
- Account has one row per account.
- Transaction has many rows per account at the transaction grain.
To make a Customer selection reach Transaction, configure Customer to filter CustomerAccount, deliberately allow the CustomerAccount-to-Account relationship to propagate the filter in both directions, and then let Account filter Transaction. That bidirectional relationship is a narrow exception required by this bridge path, not a default to copy across the model. Test it for alternate active paths and unintended filtering before release.
This structure does not automatically define the business answer. A jointly held account filtered through two customers can legitimately contribute to both customers' results, but adding both customer results may double-count the account total. The model owner must document whether attribution is full, allocated, distinct, or intentionally non-additive. If allocation is required, the bridge needs an appropriate weighting attribute and the calculation layer must apply the documented rule.
Design the bridge as a governed association
A reliable bridge design follows these principles:
- Give the bridge an explicit association grain and enforce one row per valid key combination.
- Relate dimensions to the bridge with keys whose one sides are genuinely unique.
- Connect the association to facts through an intentional dimension path instead of joining two facts directly.
- Enable only the filter direction required for the business question, then test for competing active paths.
- Keep descriptive business attributes on dimensions; keep association attributes, such as effective dates or allocation weights, on the bridge when they describe the association itself.
- Define additive behavior before publishing measures that traverse the bridge.
A direct many-to-many relationship can be supported by the model, but support does not make it the clearest architecture. Prefer an explicit bridge when users or maintainers need to understand the association, validate its members, attach association-level rules, or control double counting. Use a direct many-to-many relationship only when its semantics are simple, documented, and verified across the required report interactions.
Build Trustworthy Business Semantics
Relationships are trustworthy only when the model's visible interface agrees with them. Treat the semantic model as a contract for report authors:
- Publish dimensions and attributes with business-facing names and descriptions.
- Hide foreign keys, bridge keys, and other technical columns that are not intended for direct analysis.
- Use a dedicated, complete Date dimension for governed time filtering when the business requires consistent calendar or fiscal behavior.
- Centralize certified business calculations as explicit measures instead of encouraging implicit aggregation of every numeric column.
- Apply default summarization and formatting that match the meaning of each field.
- Organize hierarchies only when their levels have a valid drill path.
- Document bridge attribution, non-additive measures, and alternate relationship paths where report authors will find them.
The Microsoft Fabric semantic-model documentation describes semantic models as the analytical layer over Fabric data and identifies relationships, measures, and business-friendly naming as part of model preparation. Those features should reinforce one interpretation of the data rather than patch conflicting interpretations at report level.
Validate the Model as a Connected System
Test relationships before adding sophisticated calculations. A small validation matrix exposes most semantic defects:
| Test | Expected evidence |
|---|---|
| Unfiltered fact total | Matches a trusted source total at the declared fact grain |
| One dimension member | Returns only facts mapped to that member |
| Unknown or unmatched key | Follows the documented missing-member treatment |
| Two simultaneous dimension filters | Produces their intended intersection without losing valid rows |
| Bridge member with one association | Matches the corresponding target entity total |
| Bridge member with multiple associations | Follows the documented attribution rule |
| Subtotal and grand total | Reflect the business aggregation rule rather than accidental row addition |
| Alternate date or role | Uses only the intended relationship path |
Then test representative report interactions. Place attributes from different dimensions together, combine slicers, drill through hierarchies, and compare results with source queries at controlled grains. If a result changes when an unrelated dimension is added, inspect filter paths and bridge behavior before changing a measure.
These logical tests apply regardless of how tables are stored. Import, DirectQuery, Dual, composite models, and large-model storage introduce separate performance and freshness decisions covered in DP-600: Choosing Power BI Semantic Model Storage Modes and Composite Models. A storage choice cannot repair ambiguous business semantics.
Common Semantic-Model Design Mistakes
Treating every source table as a user-facing entity
Operational tables often mix multiple grains or expose implementation details. Assign a clear fact, dimension, or bridge role and hide technical structures that do not belong in the analytical interface.
Declaring many-to-many to bypass duplicate keys
Duplicate values on an intended dimension key are a data-quality or grain problem. A many-to-many setting can make the model load while leaving totals and filter meaning unreliable.
Enabling bidirectional filtering everywhere
Broad bidirectional filtering increases coupling and can create hidden fact-to-fact influence. Start with dimension-to-fact filtering and add exceptions only for a documented path.
Ignoring bridge aggregation behavior
A bridge answers membership, but membership alone does not determine allocation. Define what a shared member contributes to detail rows and totals.
Repairing relationships inside every measure
Repeated calculation-specific filter manipulation makes business meaning difficult to govern. Correct reusable relationship semantics in the model; reserve DAX for calculations that genuinely require a different context.
Certification Relevance
The current DP-600 study guide includes star schemas, bridge tables, and many-to-many relationships within the skills for designing and building semantic models. The practical competency is architectural: identify table roles and grain, verify key uniqueness, choose cardinality, control filter propagation, and prove that shared dimensions and bridges produce defensible results.
Preparation should therefore focus on explaining why a relationship is safe, predicting how a filter reaches a fact, and validating totals under ordinary and many-to-many scenarios. This is educational modeling practice, not a reconstruction of exam questions.
Conclusion
Reliable Power BI semantic models make business meaning explicit. Preserve star-schema roles, use one-to-many cardinality when keys support it, default to dimension-to-fact filter direction, and introduce bridges when a real many-to-many association needs governed propagation and aggregation rules. Validate the complete filter path—including shared members and totals—before layering calculations or storage decisions onto the model.
Authoritative Sources
- Study guide for Exam DP-600
- Understand star schema in Power BI
- Many-to-many relationship guidance in Power BI Desktop
- Semantic models in Microsoft Fabric
- Power BI guidance documentation