
Study & Preparation
CCAR-F AI Evaluation: Troubleshooting, Graders, and Reliability Patterns Explained
About this video
AI systems cannot become production-ready by measuring only whether responses look correct. In this video, we explore how architects build reliable Claude systems through evaluation frameworks, evidence-first troubleshooting, failure classification, and human escalation design. You’ll learn: - Why single accuracy scores are insufficient - How to define multidimensional AI success criteria - When to use deterministic graders versus model-based evaluation - How to troubleshoot agent failures using traces and execution evidence - How to classify transient versus semantic failures - How to design safe human-in-the-loop escalation paths - Why evaluation systems are different from context optimization techniques For CCAR-F candidates, the key lesson is understanding that reliability comes from architecture discipline. Models generate intelligence. Applications define correctness, safety, and operational control. Build systematically, evaluate rigorously, and design AI systems that can be trusted. #CCARF #Claude #AIArchitecture
Keep watching
 8:05
Study & Preparation
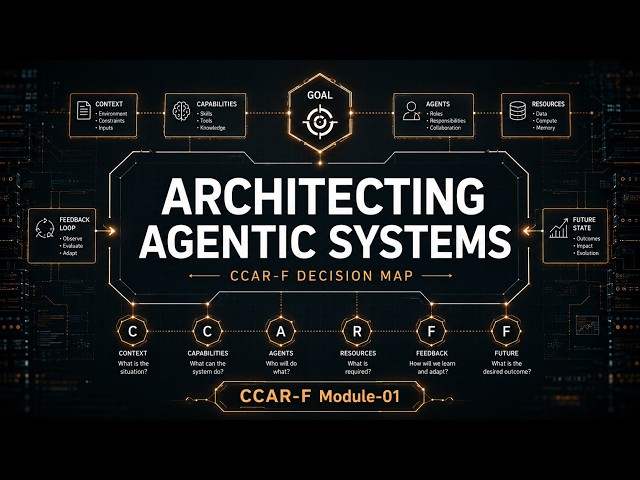
CCAR-F Architect Playbook: Designing Claude AI Solutions with the Decision Map
 9:46
Study & Preparation
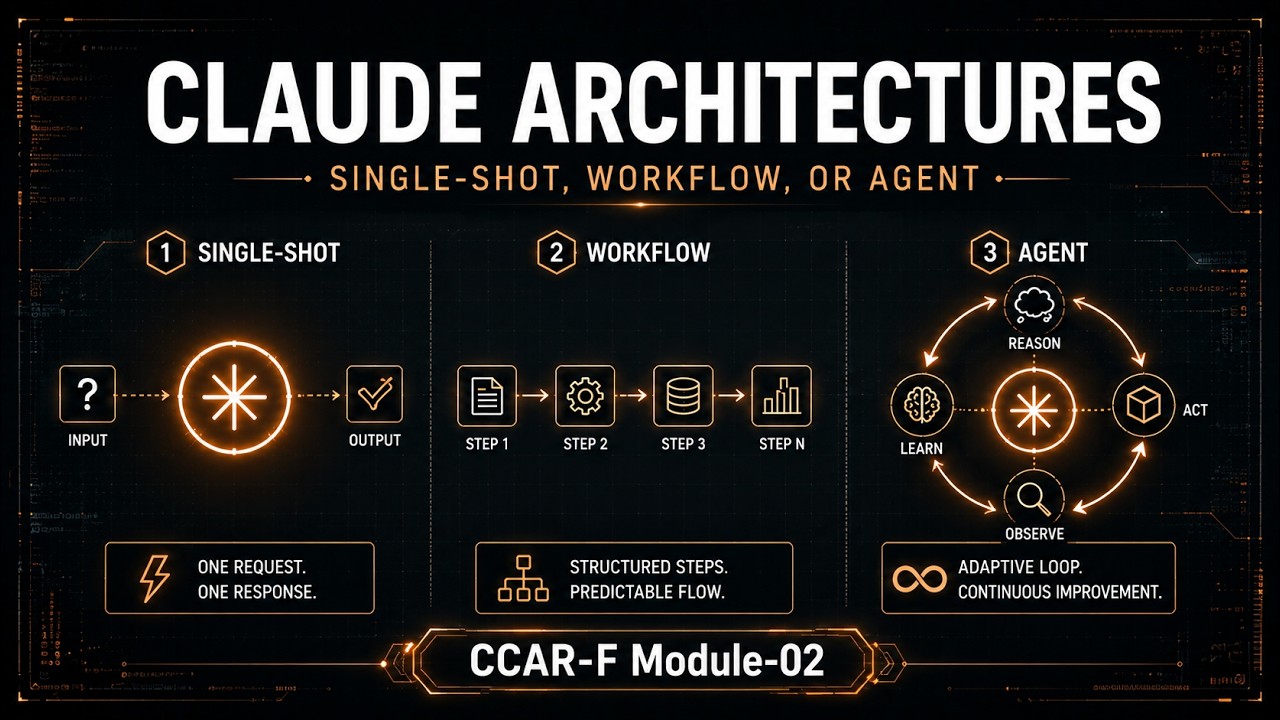
CCAR-F Architecture Patterns: Single-Shot, Workflow, and Agentic Claude Systems
 6:55
Study & Preparation
CCAR-F Claude Agent SDK: Runtime Controls, Sessions, and Permissions Explained
 9:16
Study & Preparation
CCAR-F Agent Orchestration: Claude Subagents, Permissions, and Delegation Explained
 7:46
Study & Preparation
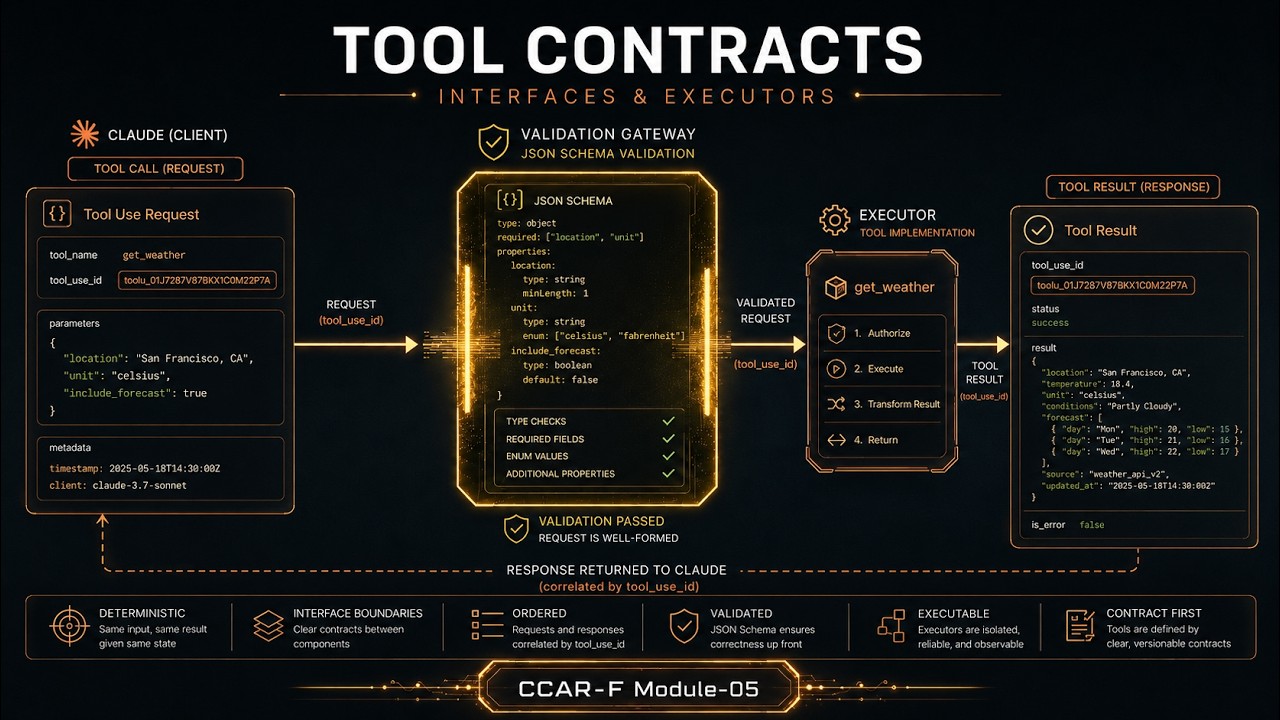
CCAR-F Claude Tool Use: Designing Secure Tool Interfaces and Execution Contracts
 8:26
Study & Preparation