
Introduction
Change an embedding model when a controlled comparison shows that its representation of your queries and content is a material cause of retrieval failures. Consider domain adaptation only when simpler corrections are insufficient, suitable training evidence exists, and the chosen model and service explicitly support that training workflow. Missing documents, broken content preparation, or incompatible query vectors need correction before a training project.
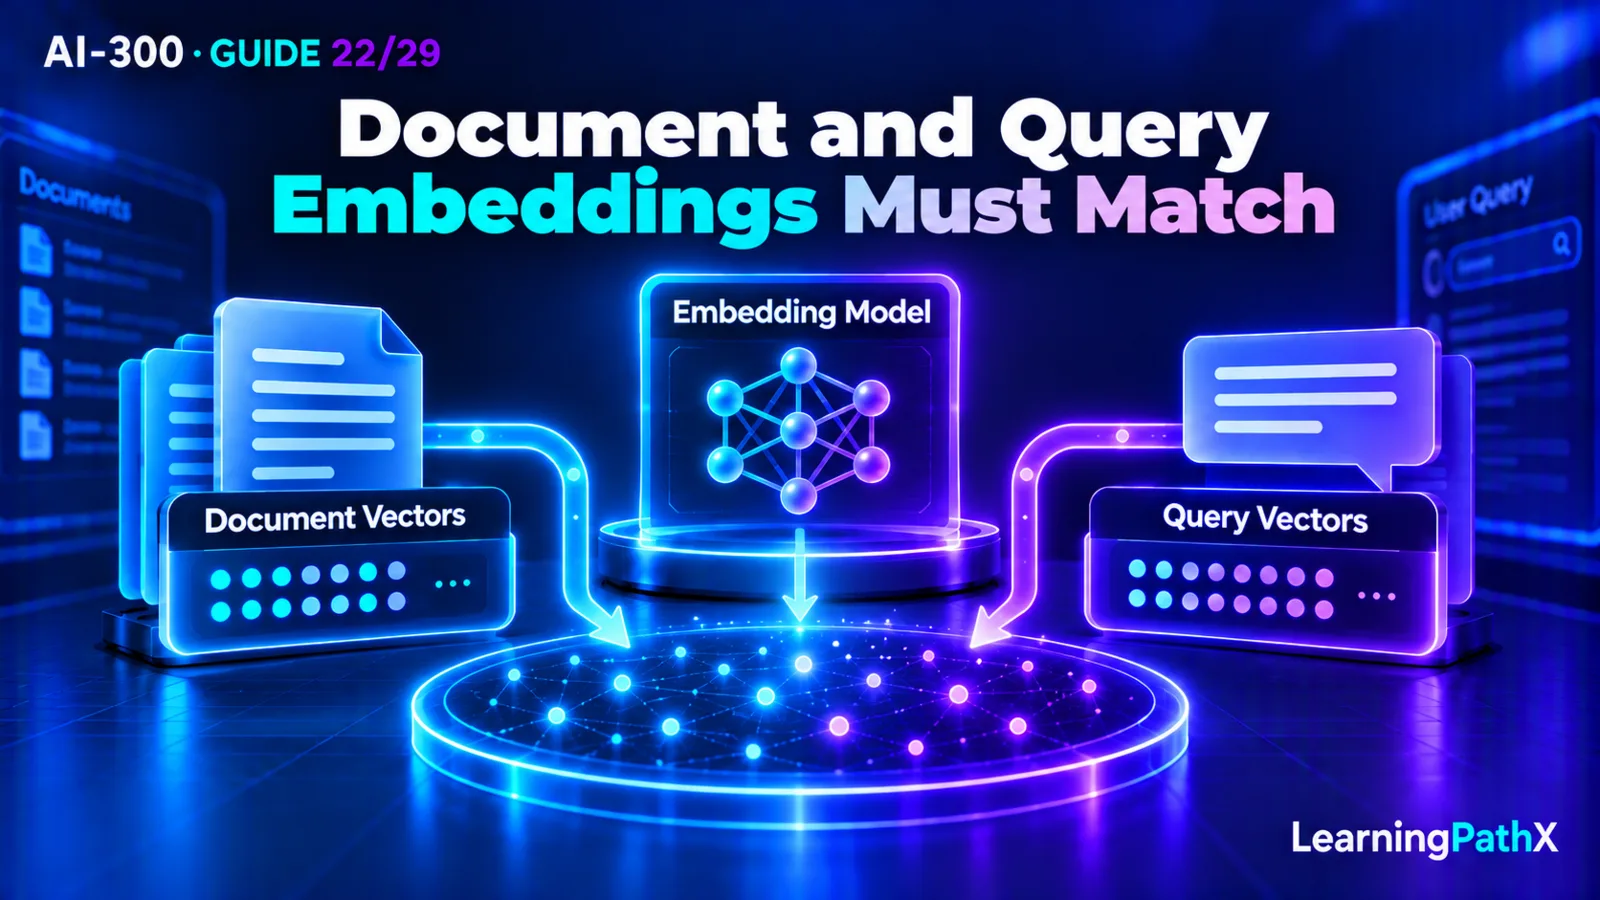
Treat a model change as a change to the retrieval system, not just an endpoint setting. Azure AI Search requires the same embedding model for indexing and querying. A candidate therefore needs compatible document vectors, query generation, index configuration, evaluation evidence and a recoverable transition. This guide supplies a decision framework; it does not invent an embedding-training API or report an executed comparison.
What an Embedding Model Contributes
An embedding model converts content into vectors used to compare representations. In vector retrieval, the query must be represented in the same embedding space as the indexed content. Equal vector lengths do not establish that two models produce interchangeable representations.
Azure AI Search does not host embedding models. Integrated vectorization connects its indexing and query facilities to external models; manual vectorization supplies vectors generated by the application. Both approaches still require a deliberate model choice and usable access to that model. Moving vector generation into an integrated workflow does not remove this compatibility contract.
Start with the retrieval architecture in AI-300: Designing Vector, Keyword, and Hybrid RAG Retrieval. The question here is whether the representation should change, rather than how fusion, semantic reranking or context selection works.
Why Error Attribution Comes Before Adaptation
Consider an illustrative maintenance corpus. Users describe a machine as “hunting at idle,” while relevant manuals describe unstable idle speed. A candidate embedding model might improve this terminology match. That is a hypothesis to test, not evidence that adaptation is already needed.
First inspect the actual answer-bearing passage. If it was omitted during ingestion, no embedding model can retrieve its absent vector. If a chunk separates the symptom from its explanation, content preparation may be the appropriate change. If retrieval finds the passage but the application removes it before generation, the embedding model is not the demonstrated failure.
Use a recommended investigation record that identifies the query, expected evidence, indexed unit, retrieved candidates and material reaching the application. Preserve unsuccessful cases alongside ordinary queries. A representation change deserves investigation when useful evidence is present and eligible but the selected model repeatedly fails to connect it with the intended query meaning.
Selecting and Adapting Embedding Models
Choose the smallest justified intervention
| Observed evidence | Candidate intervention | Evidence needed before advancing |
|---|---|---|
| The required passage is absent or incomplete | Repair ingestion or chunk preparation | The intended passage exists in a usable indexed unit |
| Critical identifiers are lost in retrieval | Reassess the text/vector retrieval design | Representative identifier queries recover the correct evidence |
| Eligible passages are present but domain paraphrases fail | Compare supported embedding models | A fixed query/evidence set shows a useful relevance change |
| A supported pretrained candidate still has a consistent domain gap | Investigate permitted domain adaptation | Explicit training support, reviewed data and independent evaluation |
| Relevant evidence reaches generation but answers remain wrong | Investigate application behavior | Trace evidence identifies a generation or input-handling failure |
This is an editorial decision aid, not a vendor diagnostic classifier. Several failures can coexist. Correct one demonstrated cause and reassess rather than assuming that a larger model or additional training addresses every layer.
Compare candidates under a stable retrieval contract
Define representative queries and the passages that would support acceptable answers. Include ordinary wording, domain paraphrases, important identifiers and questions that the corpus cannot answer. Review those relevance judgments independently of whichever model currently ranks a passage first.
For a recommended model comparison, hold the source snapshot, chunk boundaries, eligible-content rules and relevant query settings stable. Generate document and query vectors with each candidate's matching model, using a compatible index configuration for that candidate. Record any unavoidable difference rather than presenting it as an isolated model effect.
Inspect whether expected evidence appears at the useful retrieval depth, which irrelevant passages replace it, and whether important query groups regress. Also measure the latency, vector-storage footprint and operating requirements relevant to your workload. These are assessment dimensions, not claims that any particular model is cheaper, faster or more accurate.
The maintenance example might reveal improved domain-paraphrase retrieval but weaker exact-code cases. That result would require a tradeoff decision or another retrieval intervention, rather than unconditional promotion. No measured result is asserted here. Detailed controlled configuration experiments belong in AI-300: Lab: Comparing RAG Retrieval Configurations.
Establish that adaptation is an available operation
Microsoft's embedding guidance identifies domain-specific fine-tuning as an option to consider. That general advice does not establish training support for every hosted embedding model. A deployed embedding inference endpoint is evidence of serving access, not permission or capability to train it.
Before choosing adaptation, verify the exact model, its documented training route, supported training environment, required data and compatible serving path. Foundry's fine-tuning overview likewise warns against assuming that support for one model, method or modality establishes another combination. Do not substitute a generative-model training example for an embedding-model workflow.
If a supported route cannot be established, keep adaptation unapproved and consider a supported pretrained model or a different retrieval intervention. Do not invent a portal switch or Azure OpenAI embedding-training endpoint to complete the plan.
For a model that explicitly permits adaptation, a recommended preparation process is to define the domain retrieval error, curate authorized examples suited to that documented method, and retain evaluation cases outside training. Inspect misleading similarities and regressions as well as desired matches. Training loss or familiarity with the domain vocabulary cannot replace independent retrieval evidence.
Plan the Vector Transition Before Promotion
A changed embedding model requires regenerating document vectors and using the matching model for queries. Reusing old document vectors with a new query model is not a valid migration merely because a request succeeds or the dimensions match.
Recommend preparing a separate compatible candidate retrieval artifact, validating its content coverage, and comparing it with the retained baseline before cutover. The exact index or field design must follow the chosen supported configuration. Record how query routing selects the matching artifact and model together; avoid an intermediate state that mixes the two representations.
Retain the prior usable vector artifact and its model/configuration reference until the recovery criteria are satisfied. A rollback needs a compatible query path as well as old documents. Document who can switch the application, what observation triggers that switch and how the restored path will be checked.
Account for re-vectorization work, temporary duplicate storage, model access and retained resources before starting. Define cleanup ownership after acceptance or rejection. These are recommended operating controls; no cost estimate, automatic migration feature or executed cutover is claimed.
Technical Value of a Reviewable Decision
The handoff should explain the observed error, alternatives considered, exact candidate model/configuration, corpus and query identities, relevance judgments, results and important regressions. For adaptation, add the verified training route and training/evaluation separation. For deployment, add compatible vector/query references and recovery evidence.
That record lets the next engineer distinguish “the model changed” from “the whole retrieval experiment changed.” A useful rejection is equally specific: unavailable training support, no demonstrated relevance gain, an unacceptable regression or an operating constraint can all justify retaining the current model.
Common Learning Challenges
- Training before checking that the correct evidence exists in the index.
- Confusing equal vector dimensions with a common embedding space.
- Comparing models while changing chunks, corpus eligibility and retrieval settings without recording the differences.
- Assuming a hosted model's inference availability implies fine-tuning support.
- Measuring only training progress or a few attractive search results.
- Switching query generation while leaving document vectors on the previous representation.
- Deleting the baseline before verifying a compatible recovery path.
Conclusion
Select an embedding intervention from a demonstrated retrieval failure. Compare supported models against stable evidence, consider adaptation only through an explicit supported route, and preserve an independent evaluation. Promote a matching document-vector and query-model combination with a practical recovery plan.
Authoritative Sources
- Relevance in vector search
- Generate embeddings for search queries and documents
- Fine-tuning in Microsoft Foundry